Find out how AI video generation works and the fascinating process of turning written ideas into dynamic videos effortlessly.
How AI Video Generation Actually Works: Inside Models Like Veo 3
Estimated reading time: 5 minutes
A few years ago, making even a short video clip meant a camera, good lighting, and hours of editing. Today, some AI models can generate a realistic video clip from nothing but a written sentence. How a computer turns the words “a dog running through a snowy forest at sunset” into a video? Here, you’re asking one of the more fascinating questions in AI right now.
From Text to Motion: What’s Actually Happening in AI video generation
AI video generation models like Veo 3 don’t work by searching for existing footage and stitching it together. They generate every frame from scratch, based on patterns learned from studying enormous amounts of video data during training.
Here’s the simplified version of how it works. The model first breaks a text prompt down into concepts it understands: objects, actions, lighting, camera movement, style. It then builds a sequence of frames that match those concepts, frame by frame. At the same time, it keeps track of how objects should move and change over time. Because of this, the motion looks smooth and physically believable rather than jumpy or inconsistent.
That last part is the hardest problem in the field. Getting a single realistic image right is difficult enough. Getting hundreds of frames in a row to stay consistent is much harder. A person’s face shouldn’t randomly change shape between frames. A car shouldn’t flicker in and out of existence. That requires the model to understand something closer to physics and continuity than a still-image generator ever needed to.
Also Read: Explore Your Creativity with Google’s Free Veo 3
Why This Field Moved So Fast
Video generation lagged behind image generation for a simple reason: video is enormously more data. A single second of video can contain 24 to 30 separate frames, and each one needs to connect logically to the ones before and after it. Training a model to handle that much complexity requires far more computing power and far more carefully labeled data than training an image generator.
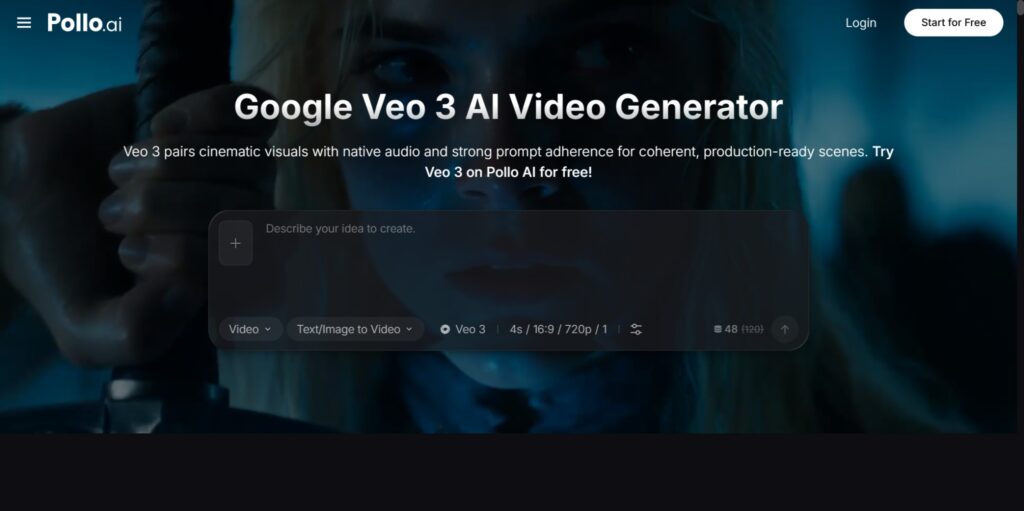
Models like Veo 3, available through Pollo AI’s Creative Studio, represent a major jump in how coherent and controllable that generated motion has become. Early text-to-video models from just two or three years ago produced short, blurry, often distorted clips. Current AI models can certainly follow detailed camera instructions. They can execute slow pans and maintain a precise depth of field. Also, they keep characters and objects consistent throughout the footage.
What Happens After the Video Is Generated
A generated video clip is rarely the finished product on its own. Creators, students working on projects, and professionals often need something more. They might pull a single frame out to use as a thumbnail, clean up a small visual detail, or generate a matching still image in the same art style as the video.
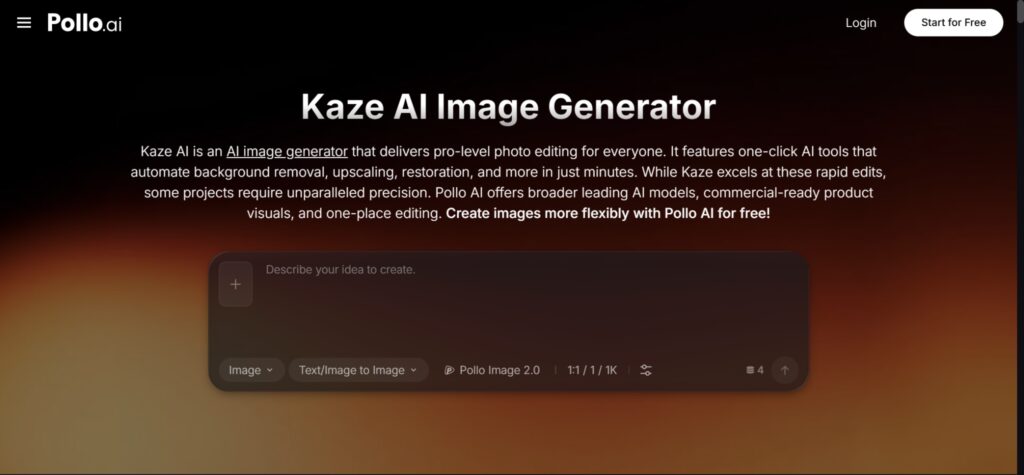
This is where an image tool paired with the video model becomes useful. Kaze AI, available alongside Veo 3 inside Pollo AI’s Creative Studio, handles this kind of follow-up work: sharpening a specific frame, removing an unwanted object, or generating a companion image that matches the video’s visual style. It’s a good example of how AI tools increasingly work together in a pipeline rather than as one single do-everything model.
Where This Technology Is Headed
Researchers are still working on some genuinely hard open problems in this field. Keeping longer videos consistent over several minutes instead of just seconds. Making sure generated motion follows real physics accurately, like how a splash of water should actually behave. Reducing the enormous amount of computing power these models require to run.
For students interested in this area, video generation sits at the intersection of computer vision, physics simulation, and machine learning, which makes it one of the more genuinely interdisciplinary corners of AI research right now. It’s also a fast-growing field professionally, with roles opening up in model training, video AI product development, and the entirely new job category of prompt engineering for generative video.
Also Read: The Application of Conversational AI and NLP Pipelines for Automated Video Generation
AI video generation: The Bigger Picture
AI video generation is a good example of how quickly a research problem can move from “barely working” to “genuinely useful” once the right combination of data, computing power, and model design comes together. A few years ago, this kind of technology existed mostly in research papers. Now it runs inside consumer tools that anyone curious enough can try. Understanding roughly how it works, breaking a scene into concepts, generating frame by frame, keeping motion consistent, is a solid foundation for anyone who wants to go deeper into computer vision or generative AI as a field of study or a future career.
- Author
- Latest Posts
Deven Nandapurkar is a Software Engineer, Project Lead; working at the strategic intersection of software engineering, productivity science, and emerging technologies. Driven by a core philosophy of “building things worth building,” he leads cross-functional teams and drives end-to-end technical strategy—from early-stage conceptualization through production-grade deployment.
A Computer Engineering graduate from Pune University, Deven brings a sharp systems-thinking approach to technical leadership, honed by years of managing high-stakes engineering projects and leading teams to top placements in national and international hackathons, including the NASA Space Apps Challenge and the Peerlist GenAI Hackathon.
Deven explores how human cognition and emerging technology converge. He regularly writes about cognitive performance optimization, attention management, AI integration, and the evolving dynamics of the modern workforce – offering actionable frameworks for professionals seeking to maximize their productivity and thrive alongside intelligent systems.