Explore the basics with our introduction to machine learning for beginners. Understand how machines learn from data and patterns.
Machine Learning: A Comprehensive Guide (Definition, Types & Applications)
Estimated reading time: 15 minutes
When software filters spam, predicts demand, or flags risk, it uses patterns. Basically, those patterns come from data, not fixed rules alone. This is why machine learning matters today. It helps systems improve from examples. Yet, it does not replace human judgment. A model can fail when data changes. It can also copy unfair patterns. So, people need clear explanations before trusting results. This guide answers what machine learning is in plain language. Particularly, it covers how ML works, major learning types, useful applications, and practical limits. It also explains where humans remain essential. Above all, good machine learning begins with a clear problem. Eventually, it ends with careful testing in real conditions.
Editorial note: Updated and co-authored by Anvita Kashikar. Last reviewed: August 2026. This educational guide explains concepts, not medical, legal, or financial advice.
Key Takeaways
- Machine learning helps software learn patterns from data.
- Supervised, unsupervised, and reinforcement learning solve different problems.
- Model quality depends on data, evaluation, and real-world monitoring.
- Human review remains essential for high-impact decisions.
- Machine learning supports decisions; it does not guarantee correctness.
What is Machine Learning?
Machine learning is a part of artificial intelligence. It builds models from examples. The models then estimate outcomes for new inputs. In other words, programmers do not write every rule. They define a goal and prepare data. The system then searches for useful relationships. A spam filter offers a simple example. It learns signals from labeled emails. Later, it estimates whether new mail is spam. That estimate is a prediction, not proven truth. Machine learning therefore differs from ordinary rule-based software. Traditional programs follow stated instructions. Conversely, ML systems learn a statistical pattern from training data. This distinction matters when systems meet unfamiliar cases. A model can perform well during testing. Still, it may fail after conditions change. Clear evaluation reduces this risk.
Machine Learning, AI, and Deep Learning
Artificial intelligence is the broader field. It includes rule systems, planning, language tools, and learning systems. After all, machine learning is one part of AI. Similarly, deep learning is one part of machine learning. It uses layered neural networks. Evidently, these networks often work well with images, sound, and text. However, deep learning is not always the best choice. It can need more data and computing power.
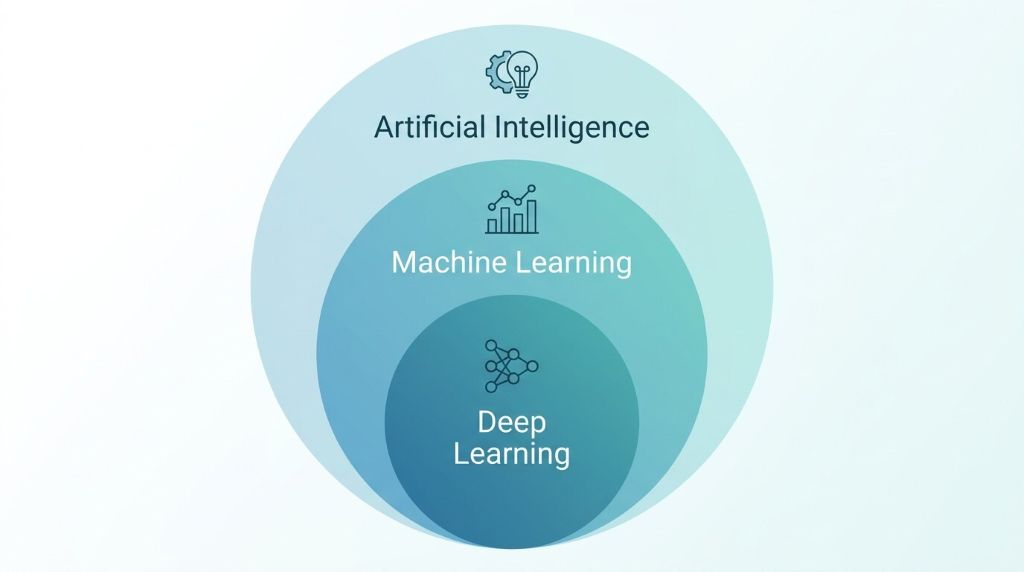
Classical models can be clearer and cheaper. The right method depends on the problem. It also depends on available data. To compare both approaches, read ENTECH’s guide to machine learning versus deep learning. The comparison helps readers avoid treating every AI problem alike. In fact, a simple model may be safer. It can reveal why a decision occurred. This is valuable in regulated settings.
“Machine Learning is the field of study that gives computers the ability to learn without being explicitly programmed.”
~ Arthur Samuel
Why the Definition Needs Care
The phrase “learns from data” can mislead readers. A model does not learn like a person. It does not hold beliefs or intentions. It estimates patterns from measured examples. The examples reflect collection choices. They can include missing values, mistakes, or bias. Therefore, good outcomes require more than an algorithm. Teams must define success precisely. They must check whether training data matches use data. They must also test performance across relevant groups. A model trained on older sales data may miss a new trend. A model trained in one hospital may not generalize elsewhere. These limits do not make ML useless. Instead, they show why context matters. Good teams treat models as tools. They set boundaries before using outputs.
How ML Works
Machine learning follows a practical cycle. First, a team defines one decision. For example, it may predict delivery delays. Next, the team gathers relevant data. It checks quality, permissions, and missing fields. After that, it transforms inputs into usable features. A feature may be distance, weather, or order volume. The team then chooses a model. Afterward, it trains the model using past examples. Finally, the model adjusts internal parameters to reduce error.
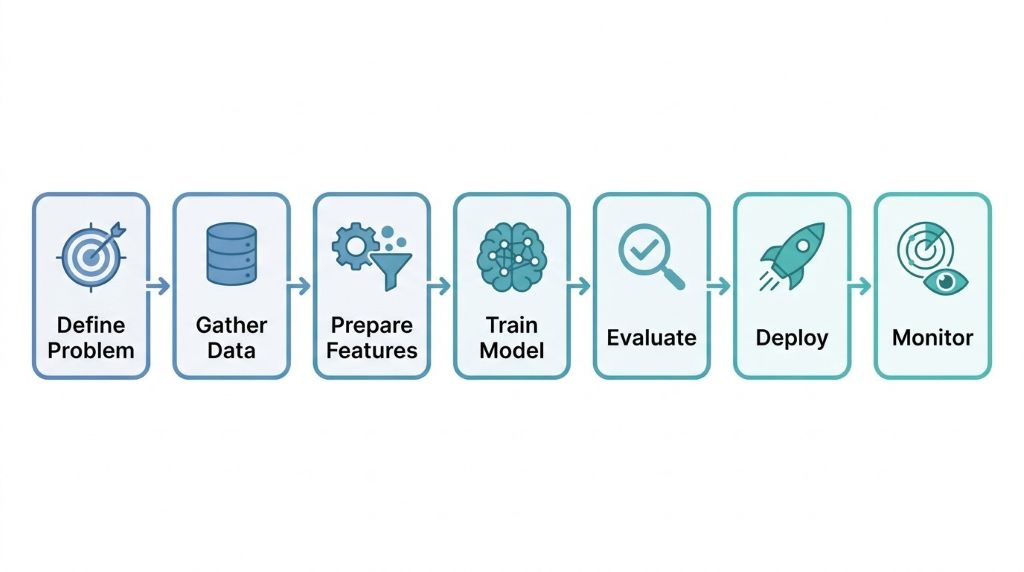
At this point, evaluation begins. A separate test set estimates future performance. This separation prevents false confidence. Finally, the team deploys and monitors the model. Monitoring checks accuracy, fairness, latency, and data drift. This cycle turns evidence into a useful estimate.
Training, Validation, and Testing
Training data teaches the model. Validation data helps teams select settings. Test data estimates final performance. Each set needs careful separation. Otherwise, information can leak between stages. Leakage can make results look much better. Yet, the model may later fail. Consider a hospital prediction task. If one patient appears in both sets, results can inflate. The model may partly memorize that patient. Proper splitting protects the evaluation.
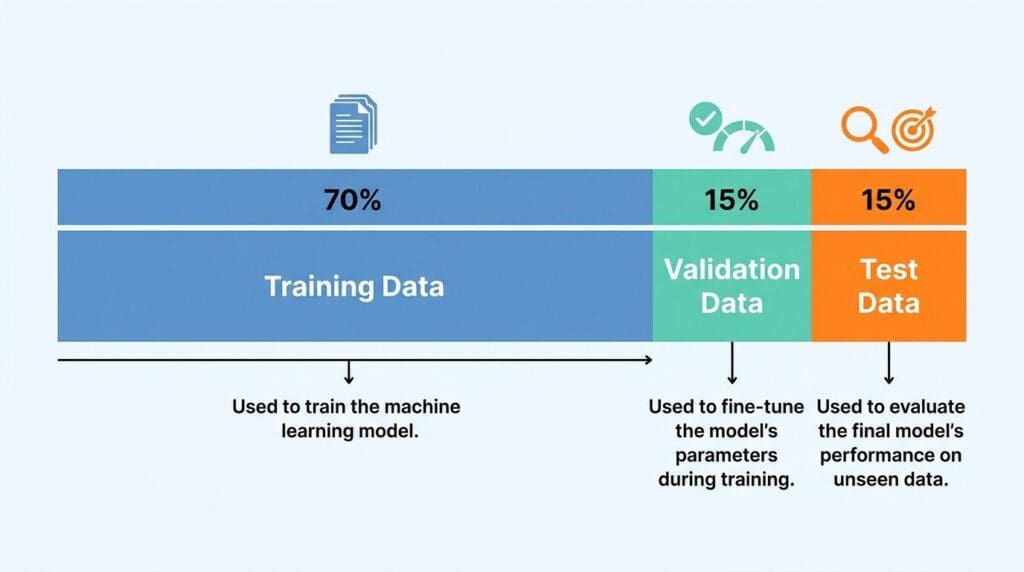
Teams should also define suitable metrics. Accuracy alone can hide serious problems. A rare disease detector may show high accuracy. Still, it could miss many true cases. Precision, recall, calibration, and error costs matter too. Prior to deployment, teams should test realistic conditions. They should review important failures with domain experts.
Features, Parameters, and Generalization
Features are input signals used by a model. Parameters are values learned during training. For example, a price model might use location. It might also use property size. The model learns how those features relate. However, more features do not guarantee better results. Irrelevant signals can cause overfitting. Overfitting means the model fits training quirks. It then performs poorly on new data. Regularization, simpler models, and stronger validation can help. At the same time, feature choices can create ethical concerns. A proxy variable may reflect social disadvantage. Teams should document every important feature. They should explain why it helps the decision. This practice supports accountability. It also makes future audits easier.
Types of Machine Learning
The three common types of machine learning differ by feedback. Supervised learning uses labeled examples. Each record includes an input and answer. Unsupervised learning uses data without target labels. It seeks structure or groups. Reinforcement learning uses actions and rewards. An agent chooses actions over time. It learns policies that seek higher rewards. These categories are useful teaching tools. Yet, real systems can combine methods. Semi-supervised learning mixes labeled and unlabeled data. Self-supervised methods create training signals from data itself. The right choice depends on the task. It also depends on label availability. To put it differently, the learning setup matters first. A powerful algorithm cannot fix a mismatched objective. Clear goals make model selection easier.

Supervised Learning
Supervised learning predicts a known outcome. Classification predicts a category. Spam detection is a classification task. Regression predicts a number. House-price estimation is a regression task. The model learns from examples with answers. Those answers must be accurate. Poor labels create poor predictions. Teams should define labeling rules before annotation begins. They should measure disagreement among reviewers. They should also examine class imbalance. Fraud cases are often rare. A model can ignore fraud and appear accurate. Therefore, evaluation should reflect actual consequences. Thresholds should match real business or safety needs. Supervised models can be highly useful. Still, they require ongoing checks after release. Customer behavior and markets can change. A reliable model needs monitoring, not one-time training.
Unsupervised and Reinforcement Learning
Unsupervised learning finds patterns without a target answer. Clustering may group customers by behavior. Dimensionality reduction may simplify complex data. These methods can support exploration. However, groups are not automatically meaningful. Human experts must interpret them. Reinforcement learning solves sequential decisions. A system receives rewards after actions. It may learn game strategies or control policies. However, reward design is difficult. A poorly designed reward can produce harmful behavior. For example, maximizing clicks may reduce content quality. Teams should test reward rules carefully. They should create safety limits before live use. In either case, human oversight remains necessary. Models can suggest patterns or actions. People must decide whether those outputs fit real goals.
Common Algorithms and Model Choices
Different algorithms make different trade-offs. Linear regression is simple and useful. It estimates continuous values from inputs. Logistic regression estimates class probabilities. Decision trees use readable decision rules. Random forests combine many trees. They often improve stability. Support vector machines can separate complex groups. K-means clustering groups similar observations. Neural networks can capture complex relationships. However, they may be harder to explain. There is no universally best algorithm. A model should match the data, objective, and risk. As a matter of fact, a baseline model should come first. It gives teams a reference point. A complex model must beat that baseline meaningfully. Otherwise, extra complexity adds little value. The best solution often balances accuracy, cost, and interpretability.
Choosing a Model Responsibly
Model choice should begin with the decision. Ask what output users need. Ask how errors affect people. Then select metrics and safeguards. In healthcare, missed cases can harm patients. In lending, biased outcomes can exclude people. These settings need stronger validation. They also need clear accountability. Research on health-care implementation reports recurring barriers. These include infrastructure, organizational culture, trust, and stakeholder engagement (Preti et al., 2024). Therefore, technical performance is only one requirement. Teams should involve subject experts early. They should document data sources and limits. They should test subgroups before deployment. What’s more, they should give users a path to challenge results. This design improves trustworthiness. It also helps teams find real failures sooner.
Machine Learning Applications
Machine learning supports many everyday services. Search engines rank useful results. Recommendation systems suggest products or media. Banks may detect unusual transactions. Manufacturers may predict equipment failures. Farmers may estimate crop conditions. Cities may predict traffic demand. These applications share a common pattern. They use past observations to guide future action. Still, prediction is not the same as decision. A risk score should not automatically deny a loan. A health alert should not replace clinical judgment. The outcome depends on data quality and local conditions. To illustrate, a retailer can use forecasts for inventory. Yet, sudden events can break historic patterns. Teams should prepare fallback processes. Human operators should review exceptional cases. In short, ML adds decision support when its limits are clear.
Healthcare and Scientific Work
Healthcare uses machine learning for imaging support, prognosis, workflow, and research. These uses can help clinicians organize complex information. However, health models require extra care. Privacy, bias, transparency, and external validation are essential. A 2024 systematic review found implementation depends on more than accuracy. It highlighted trust, infrastructure, information access, and engagement (Preti et al., 2024). That result applies beyond healthcare. Any high-impact model needs practical adoption work. Readers can see one focused example in ENTECH’s article on affective AI in healthcare systems. Data science also supports this process. It prepares, explores, and evaluates data. For a broader career perspective, visit why study data science. These fields work together to turn raw records into useful evidence.
Business, Security, and Public Services
Businesses use ML for forecasting, personalization, and anomaly detection. Security teams use it to prioritize alerts. Public agencies may use it for service planning. These uses require governance. A score can influence real people. Therefore, organizations should explain intended use. Specifically, they should record who owns each model. For example, they should set review dates. Additionally, they should monitor unexpected changes. At the same time, users need understandable communications. They should know when automated support shaped a process. They should also know how to seek review. This is especially important for high-impact decisions. Teams must protect data with access controls. They must collect only necessary information. They must delete data responsibly. These measures support privacy and public confidence. They also reduce operational and legal risk.
Limits, Risks, and Responsible Use
Machine learning can fail in predictable ways. For example, it can learn bias from historic data. Particularly, it can overfit small samples. It can drift after deployment. It can produce confident but wrong outputs. All things considered, these problems deserve planned safeguards. First, teams should define the model’s purpose. Next, they should identify people affected. Then, they should assess likely harms. After that, they should test performance across relevant groups. As an illustration, they should document findings in a model card. They should set human review rules. At last, they should monitor live behavior. The process should include incident response. It should also include clear retirement criteria. This approach helps teams avoid “set and forget” systems. Responsible use makes reliability a continuing task.
Bias, Privacy, and Explainability
Bias can enter through sampling, labels, and design choices. A dataset may exclude important communities. A label may reflect past unequal treatment. A feature may stand in for protected traits. Teams should investigate these risks before release. Privacy needs equal attention. Particularly, models can expose sensitive data through weak governance. All things considered, organizations should use lawful data practices. They should reduce identifiers where possible. They should control access and retention. Explainability also matters. Users may need reasons for a result. As has been noted, this does not mean every model must be simple. It means the explanation should match the decision’s stakes. In high-impact settings, teams should provide clear limits. They should offer human escalation routes. These practices make fairness measurable and actionable.
A Practical Responsible-ML Checklist
This checklist cannot remove every risk. However, it creates a disciplined starting point. It also makes responsibility visible. Teams should revisit these questions regularly.

A model may face new users, data, or incentives. In general, reliable ML needs technical skill and careful governance. The goal is not maximum automation. The goal is better, safer decisions. All things considered, responsible practice protects both users and organizations.
The Future of Machine Learning
Machine learning will keep changing how organizations use information. As a result, better tools may speed experimentation. Eventually, smaller models may reduce computing costs. By all means, privacy-preserving methods may support collaboration. Interpretable methods may improve oversight. Yet, progress should not mean blind automation. The most useful systems will solve clear problems. They will use suitable data. Yet, they will remain open to review. Also, they will respect people affected by their outputs. Future work will likely connect model building with stronger governance. That includes documentation, independent testing, and real-world monitoring. At the present time, the core lesson remains simple. Machine learning is valuable when people use it carefully. It turns data into estimates. At the same time, people must turn those estimates into responsible action.
Frequently Asked Questions on Machine Learning
What is machine learning in simple words?
Machine learning is a way for software to learn patterns. It uses past data to estimate future outcomes. For example, it can classify emails as spam. It can also predict delivery time. The software does not receive every rule. Instead, it learns from examples. The quality of those examples matters greatly. Poor data can create poor results. A model also needs tests on new data. This checks whether learning generalizes. Machine learning is not a thinking person. It is a statistical tool. Basically, it helps people make informed choices. Particularly, it should not make high-impact choices alone. In sum, ML learns useful patterns from data.
What are the three main types of machine learning?
The three common types are supervised, unsupervised, and reinforcement learning. Supervised learning uses labeled examples. It predicts known categories or values. Also, unsupervised learning finds groups or hidden structure. Particularly, it works without target labels. Reinforcement learning learns through rewards after actions. Specifically, it suits sequential decisions. Each type needs a different setup. Being that, a team must identify the real task first. It must also define success before training. One method is not always better. Although, the data and risk determine the best choice. In either case, teams should test results carefully. They should involve domain experts. This supports reliable use.
Is machine learning the same as artificial intelligence?
Machine learning is a part of artificial intelligence. AI is the wider field. It includes systems that reason, plan, or follow rules. Machine learning focuses on learning from data. Deep learning is a narrower ML approach. It uses multilayer neural networks. The terms often appear together. Still, they should not be treated as identical. A rule-based chatbot can be AI. It may not use machine learning. A regression model can use ML. It may not be deep learning. Precise language helps readers assess claims. It also improves project planning. Teams can then choose suitable methods. At any rate, AI is broader than ML.
Can machine learning make decisions without people?
Some systems can automate limited actions. For example, a filter can block obvious spam. However, high-impact decisions need human oversight. A model can be wrong, biased, or outdated. It may also lack context. In healthcare, a model should support trained professionals. In finance, users need fair processes. Teams should set clear operating boundaries. They should record who reviews exceptions. Additionally, they should provide an appeal process. Also, they should monitor errors after launch. Automation may save time. Yet, it must not remove accountability. The safe approach uses ML as decision support. People remain responsible for consequential outcomes.
References
Albahra, S., Gorbett, T., Robertson, S., D’Aleo, G., Kumar, S. V. S., Ockunzzi, S., Lallo, D., Hu, B., & Rashidi, H. H. (2023). Artificial intelligence and machine learning overview in pathology & laboratory medicine: A general review of data preprocessing and basic supervised concepts. Seminars in Diagnostic Pathology, 40(2), 71–87. https://doi.org/10.1053/j.semdp.2023.02.002
Ono, S., & Goto, T. (2022). Introduction to supervised machine learning in clinical epidemiology. Annals of Clinical Epidemiology, 4(3), 63–71. https://doi.org/10.37737/ace.22009
Preti, L. M., Ardito, V., Compagni, A., Petracca, F., & Cappellaro, G. (2024). Implementation of machine learning applications in health care organizations: Systematic review of empirical studies. Journal of Medical Internet Research, 26, e55897. https://doi.org/10.2196/55897
Sarker, I. H. (2021). Machine learning: Algorithms, real-world applications and research directions. SN Computer Science, 2, 160. https://doi.org/10.1007/s42979-021-00592-x
Yakimovich, A., Beaugnon, A., Huang, Y., & Ozkirimli, E. (2021). Labels in a haystack: Approaches beyond supervised learning in biomedical applications. Patterns, 2(12), 100383. https://doi.org/10.1016/j.patter.2021.100383
Machine Learning and Knowledge Extraction. (n.d.). MDPI. https://www.mdpi.com/journal/make
Machine Learning with Applications. (2024). Machine Learning with Applications, 15. https://www.sciencedirect.com/journal/machine-learning-with-applications/vol/15/suppl/C
Iberdrola. (n.d.). Machine learning: Definition, types and practical applications. https://www.iberdrola.com/about-us/our-innovation-model/machine-learning-automatic-learning
- Author
- Latest Posts

I am Anvita Kashikar, a Computer Engineering graduate with Honors in Data Science, specializing in Artificial Intelligence and Machine Learning. My academic and research interests lie in Artificial Intelligence, Machine Learning, Deep Learning, Explainable AI, Optimization Techniques, and Data Science. I am particularly passionate about leveraging AI to address complex challenges in healthcare, finance, and drug discovery.
My work is grounded in a strong foundation of mathematics, optimization, and computational intelligence. I have contributed to the development of book chapters on topics including Dijkstra’s Algorithm, Necessary and Sufficient Conditions, Saddle Point Theory, Information Entropy, Taylor’s Series, Classification and Applications of Eigenvalues and Eigenvectors, MaxOne Problem, Topology Optimization, and Sensitivity Analysis. These contributions reflect my interest in the mathematical and optimization principles that underpin modern AI systems.
I have also been actively involved in research exploring emerging applications of Artificial Intelligence and Machine Learning. My research work includes studies on interpretable deep learning using Kolmogorov-Arnold Networks (KANs) for tabular data, AI-driven drug discovery and development, and generative optimization techniques for accelerating pharmaceutical research. Several of these research papers and book chapters have been published, while others are currently under review or in various stages of the publication process.
Through my academic and research endeavors, I strive to bridge theoretical concepts with practical applications, contributing to the development of transparent, efficient, and impactful AI solutions. As an early-career researcher, I am committed to continuous learning, interdisciplinary collaboration, and advancing the responsible use of Artificial Intelligence to address real-world challenges and create meaningful societal impact.
- Author
- Latest Posts
Deven Nandapurkar is a Software Engineer, Project Lead; working at the strategic intersection of software engineering, productivity science, and emerging technologies. Driven by a core philosophy of “building things worth building,” he leads cross-functional teams and drives end-to-end technical strategy—from early-stage conceptualization through production-grade deployment.
A Computer Engineering graduate from Pune University, Deven brings a sharp systems-thinking approach to technical leadership, honed by years of managing high-stakes engineering projects and leading teams to top placements in national and international hackathons, including the NASA Space Apps Challenge and the Peerlist GenAI Hackathon.
Deven explores how human cognition and emerging technology converge. He regularly writes about cognitive performance optimization, attention management, AI integration, and the evolving dynamics of the modern workforce – offering actionable frameworks for professionals seeking to maximize their productivity and thrive alongside intelligent systems.


Great machine learning article! The Explanation of the different types of learning algorithms supervised, unsupervised, and reinforcement learning was very clear and informative.